Getting cited by Perplexity requires clearing two separate algorithmic bars: retrieval (Perplexity finds your page) and absorption (Perplexity quotes it in the answer). Most well-written pages fail the second bar, not the first. Fix your opening paragraphs, allow Perplexity’s bots, add FAQ schema, and earn third-party mentions, and you can move from invisible to cited within a few weeks to a couple of months.
Here is what that looks like in practice:
- Allow
PerplexityBotandPerplexity-Userin yourrobots.txtand CDN settings. - Open every section with a direct, specific answer in the first 1–3 sentences.
- Add named entities, dates, and verifiable data points throughout your content.
- Earn Reddit mentions and editorial coverage to build off-site trust signals.
- Implement FAQPage and HowTo schema markup on your top pages.
- Track citation appearances weekly against a fixed set of buyer prompts.
Pro Tip: Rewrite the first sentence of every major section to lead with a direct claim or number. That single change improves both retrieval relevance and answer absorption at the same time.
How Perplexity AI selects and cites sources
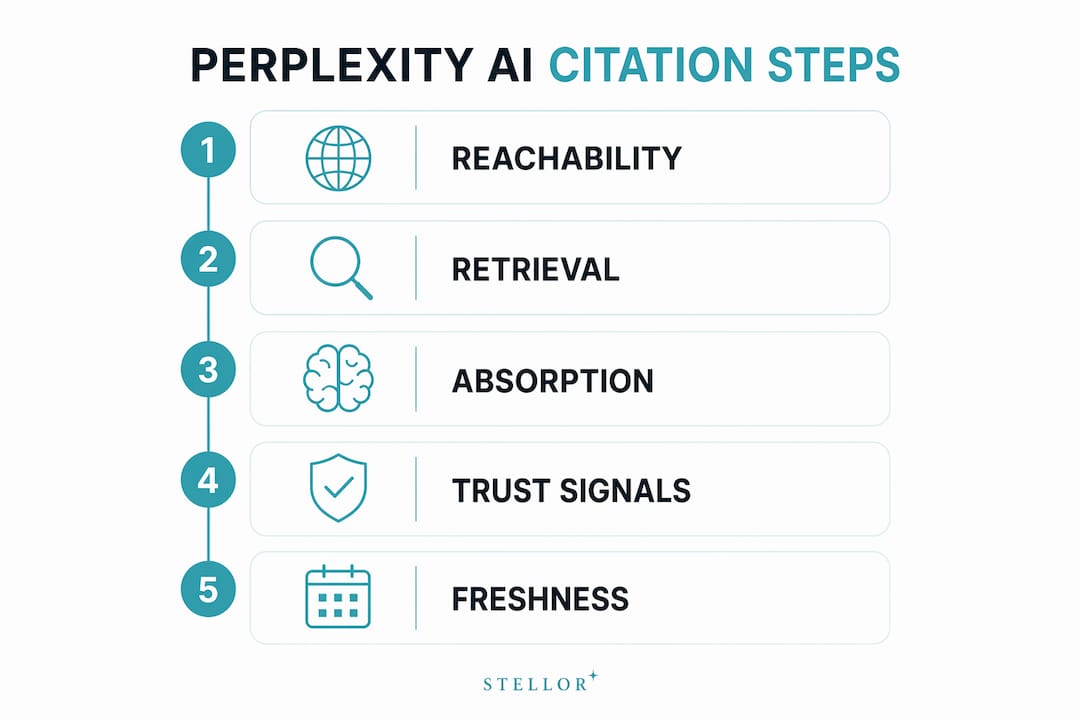
Perplexity operates a two-bar citation system: retrieval and absorption. Retrieval depends on domain authority, content freshness, and crawlability. Absorption depends on whether the model can extract a clean, quotable answer span from your page.
Perplexity retrieves multiple pages per query but cites only a few in its final answer. Clearing retrieval is necessary but not sufficient. A page can appear in the sources panel on the right side of a Perplexity response and still contribute nothing to the actual answer text.
The selection process runs through three layers. First, the crawler filters for basic crawlability and topical relevance. Second, a reranker scores structural signals: answer-first openings, heading hierarchy, and specific data points. Third, an earned authority layer weights third-party editorial coverage more heavily than brand-owned content. A page that clears layers one and two but lacks third-party validation gets retrieved and then passed over.
Perplexity differs from ChatGPT in one critical way: it retrieves live web content in real time for every query. Freshly indexed content can surface in Perplexity citations within hours of publication. That makes it the more accessible platform for newer sites without established brand recognition in training data, and the one where consistent earned media compounds fastest.
| Signal type | Bar it affects | Key factor |
|---|---|---|
| Domain authority | Retrieval | Quality backlinks and third-party mentions |
| Content freshness | Retrieval | Visible publish or update date within 12–18 months |
| Crawlability | Retrieval | PerplexityBot and Perplexity-User not blocked |
| Answer-first structure | Absorption | Direct answer in first 1–3 sentences per section |
| Named entities and data | Absorption | Specific numbers, dates, and attributed sources |
| FAQ and HowTo schema | Both | Machine-readable Q&A structure |
| Third-party mentions | Authority layer | Editorial coverage, Reddit, niche forums |
Reddit’s role in this system is worth understanding specifically. Reddit accounts for about 24% of all Perplexity citations, making it one of the largest source platforms. That is not a platform preference. Reddit’s content structure matches exactly what Perplexity’s retrieval system was trained to find: direct answers, community validation through upvotes, and first-person experience over polished brand copy.
Technical setup that lets Perplexity actually reach your pages
Before any content work matters, Perplexity’s bots need to reach your pages. This is the step most sites skip, and it quietly disqualifies more content than any other factor.
Perplexity crawls with two user agents: PerplexityBot for building its index and Perplexity-User for fetching specific URLs during a live conversation. Blocking either agent in robots.txt, a CDN firewall rule, or a “block AI scrapers” toggle removes your entire domain from the retrievable set. Cloudflare’s “Block AI Scrapers and Crawlers” setting blocks both by default.
Robots.txt and CDN configuration
Open your robots.txt and confirm neither PerplexityBot nor Perplexity-User appears in a Disallow rule. Then check your CDN or WAF (Cloudflare, Fastly, Akamai) for AI-bot blocking rules and allowlist both agents explicitly. Run a quick test: curl -A "PerplexityBot" https://yourdomain.com and confirm a 200 response, not a 403.
The llms.txt file
Add /llms.txt and /llms-full.txt files to your domain root. Perplexity’s crawler honors these files. A /llms-full.txt with your full content corpus inlined increases the surface area Perplexity can sample for citations significantly. Think of it as a table of contents written specifically for AI crawlers.
Schema markup
Pages with FAQPage schema appear more frequently in top-three citation positions compared to standard articles. Implement FAQPage, Article, and HowTo schema on your priority pages. Mirror your on-page FAQ content into FAQPage schema so the Q&A structure is machine-readable. Add Organization markup with a consistent name, category, and description across your site.
Freshness signals
A majority of top Perplexity citations show a visible publish or update date within a recent timeframe. For fast-moving topics like AI tools or platform changes, that window tightens to 60–90 days. Add visible dates to every page and genuinely update the content when you change the date. Bumping a timestamp without updating the substance does not fool the freshness signal.
| Technical action | What it fixes | Priority |
|---|---|---|
| Allowlist PerplexityBot and Perplexity-User | Retrieval access | Critical |
| Add /llms.txt and /llms-full.txt | Corpus exposure | High |
| FAQPage and HowTo schema | Absorption and citation position | High |
| Visible publish and update dates | Freshness signal | High |
| Organization schema | Entity clarity | Medium |
| Server-side rendering for key pages | Crawl reliability | Medium |
Pro Tip: If your page renders content only through client-side JavaScript, serve a server-rendered or statically generated version. Retrieval systems are far more reliable on HTML that ships with the words already in it.
Building the trust signals that push you into citations
Technical access gets you into the retrieval pool. Trust signals determine whether you survive the authority layer and get cited. This is where most brands plateau: they fix their robots.txt, add schema, and then wonder why competitive queries still return other sites.
Perplexity weighs independent third-party validation heavily. Your own page saying you are the best is a weak signal. A review platform, an industry publication, and a Reddit thread all naming you is a strong one. When Perplexity’s authority layer sees your entity mentioned across independent sources, two things happen: your retrieval probability increases, and you become more likely to be named directly in the answer even when the cited page is not yours.
Domain authority, built through quality backlinks and third-party mentions, accounts for a meaningful share of the citation signal. That percentage matters because it is the gating factor on competitive queries. Without it, well-structured content still loses to a weaker page on a more authoritative domain.
Practical tactics for building off-site trust:
- Earn Reddit presence in the right subreddits. Identify the 5 subreddits where your buyers ask questions. Build comment history over 90 days before referencing your brand. Quality and patience beat volume every time.
- Get named in niche forums. Certain niche forums collectively account for a modest share of Perplexity citations. A single well-received Hacker News comment can generate citations over the following 60 days as the page gets re-indexed.
- Pursue editorial coverage. A mention in a trade publication or a feature in an industry roundup lifts domain authority and your “discussed-about” signal simultaneously. One legitimate editorial mention moves the needle more than a hundred directory submissions.
- Earn honest reviews on platforms Perplexity cites in your category. Comparison and review platforms contribute a noticeable share of citations. Get on the lists that already rank for your category’s comparison queries.
- Publish original data. Perplexity cites primary-data documents at a higher rate than secondary commentary. One defensible data study per quarter compounds citation share over time.
For home services businesses specifically, community engagement and customer reviews play a direct role in how AI engines perceive your authority. The way customer FAQs build search credibility for home services brands mirrors exactly what Perplexity’s authority layer rewards: consistent, specific, community-validated answers.
Writing content that Perplexity actually quotes
Structure is where most well-meaning content fails. Perplexity lifts a concise claim it can attribute cleanly. If your answer is buried under three paragraphs of context-setting, a competitor who states it plainly gets quoted instead.
The fix is architectural. Every section intended to be cited must open with a direct, specific, extractable answer. Not “this guide covers,” not a definition that builds to a point. The answer, in the first sentence. Rewriting the first sentence of every major section to lead with a direct claim is the single change that moves both bars at once.
Consider the difference: “When considering vendor criteria…” loses to “The top three vendor selection criteria for B2B buyers are integration capabilities, pricing transparency, and implementation timelines.” Specificity and extractability are the same requirement.
Content structuring best practices for Perplexity absorption:
- Use question-form H2 and H3 headings that match real buyer queries. The question your customer types into a search bar should appear as a heading on your page.
- Answer in the first 1–3 sentences under each heading. Keep those answer spans under 300 words.
- Include specific numbers, dates, and named entities. “Content marketing has grown significantly” loses to a claim with a named source, a specific percentage, and a quarter.
- Turn “X vs. Y” and “best options” content into real comparison tables. Tables are among the most extractable formats Perplexity encounters.
- Add a short FAQ block covering adjacent questions from your query map, with each answer in 1–2 sentences.
- Add a “Sources” or “References” section at the bottom of long-form posts. Perplexity favors documents that themselves cite primary sources.
- Keep one idea per section. A section that tries to answer three questions gets cited for none of them cleanly.
Pro Tip: A 20-word answer that takes a position outperforms a 50-word answer that hedges. Perplexity favors direct, attributable answers over committee-edited prose that qualifies every claim.
Understanding how AI search is changing local business discovery helps frame why this content structure matters beyond just Perplexity. The same answer-first discipline that earns Perplexity citations also improves your visibility in ChatGPT, Gemini, and Claude responses.
How Trystellor tracks and improves your Perplexity citations
Monitoring citations manually is slow and incomplete. Running the same 15 buyer prompts through Perplexity every week by hand, logging results, and cross-referencing against competitors takes hours. Most teams do it once and then stop.
Trystellor automates this entire workflow. Every week, the platform queries ChatGPT, Claude, Perplexity, and Gemini using the prompts your buyers actually use, then reports back exactly where your business appears, which competitors are being cited instead, and how the citation landscape is shifting. That turns AI visibility from a vague concern into a measurable channel with clear baselines and weekly trends.
The platform’s weekly technical audits cover the specific signals AI crawlers look for: schema completeness, llms.txt readiness, structured data integrity, page speed, and internal linking depth. Issues surface in the dashboard with one-click fixes. The 4,000-site backlink network handles the off-site authority signals that domain authority depends on, without manual outreach or the reputational risk of low-quality link schemes.
The Reddit module is where Trystellor’s approach to community signals becomes concrete. The platform identifies high-intent threads in real time, drafts authentic reply suggestions for your review, and builds consistent presence in the subreddits where your buyers gather. That presence feeds directly into Perplexity’s authority layer, since Reddit accounts for a significant share of Perplexity citations.
| Trystellor feature | What it addresses | Frequency |
|---|---|---|
| LLM citation tracking | Citation rate and competitor share across Perplexity, ChatGPT, Claude, Gemini | Weekly |
| Technical site audits | Schema, llms.txt, crawlability, page speed | Weekly |
| Backlink network (4,000 sites) | Domain authority and off-site trust signals | Ongoing |
| Reddit module | Community citation signals and subreddit presence | Daily |
| 30 articles per month | Content volume, topical authority, answer-first structure | Monthly |
For citation monitoring outside of Trystellor, Google Analytics 4 requires custom channel grouping to accurately capture Perplexity referral traffic. GA4 can misclassify sessions from perplexity.ai without that configuration, which means citation-driven traffic goes untracked. Set up a dedicated AI referral channel in GA4 to measure the actual clicks your citations produce.
Post-implementation monitoring steps:
- Run the same 15–20 buyer prompts weekly and track citation count, citation quality (primary recommendation vs. passing reference), and competitor share.
- Watch the
perplexity.aireferrer in your analytics. Growth in that referrer correlates directly with citation share. - Check your server access logs for
PerplexityBotfetch frequency. A healthy site sees fetches at least 3–5 times per week across active pages. - Audit your top 20 pages quarterly for answer-span extractability. Open each page, find the H2 that mirrors the buyer question, and check whether the first 1–3 sentences contain a self-contained, quotable answer.
The ChatGPT SEO ranking factors guide for 2026 covers how these same signals translate across AI engines, since the underlying citation mechanics share more overlap than most guides acknowledge.
Trystellor gives you the infrastructure to get cited consistently
Getting cited by Perplexity once is a content win. Getting cited consistently across dozens of buyer prompts, week after week, requires infrastructure: technical health, content volume, off-site authority, and ongoing monitoring working together.
Trystellor replaces five separate vendors with one platform at $199 per month. You get 30 GEO and SEO-optimized articles published to your CMS every month, each built with the answer-first structure and schema markup Perplexity’s absorption layer requires. The 4,000-site backlink network builds the domain authority that clears retrieval on competitive queries. Weekly audits catch technical issues before they cost you citations. The Reddit module builds the community presence that feeds Perplexity’s authority layer. And the LLM tracking reports tell you exactly where you stand across Perplexity, ChatGPT, Claude, and Gemini every week.
There is no long-term contract and no credit card required for the three-day free trial. Start with a free AI Visibility Audit that shows your current citation status across 25 buyer prompts, a competitor benchmark, and a 90-day action plan. You keep the audit even if you cancel. Start your free trial and see where Perplexity is citing your competitors instead of you.
FAQ
How do you cite Perplexity as a source?
To cite Perplexity as a source in your own writing, reference the specific answer it generated along with the date you accessed it, since Perplexity retrieves live web content and answers change over time. For academic work, treat it similarly to a website citation with the URL, access date, and the query you used.
Is Perplexity good at citing sources?
Perplexity is the most citation-transparent of the major AI search engines. Every answer surfaces a numbered list of clickable sources, making it easier to verify claims than with tools that do not show their references.
How is getting cited by Perplexity different from getting cited by ChatGPT?
Perplexity retrieves live web content in real time for every query, so freshly published content can appear in citations within hours. ChatGPT relies more heavily on training data and favors established entities, making Perplexity the more accessible platform for newer sites building authority.
Does Reddit really affect Perplexity citations?
Reddit accounts for about 24% of all Perplexity citations, making it one of the largest source platforms. Earning upvoted mentions in the subreddits where your buyers ask questions is one of the fastest paths to Perplexity visibility available.
Can Trystellor help me track and improve my Perplexity citation rate?
Yes. Trystellor queries Perplexity weekly using your actual buyer prompts, reports your citation status and competitor share, and runs the technical audits, backlink building, and Reddit engagement that drive citation growth. The platform covers all four major AI engines: Perplexity, ChatGPT, Claude, and Gemini.
Key Takeaways
Getting cited by Perplexity consistently requires clearing both the retrieval bar and the absorption bar, backed by off-site trust signals that no amount of on-page optimization can replace alone.
| Point | Details |
|---|---|
| Two-bar system | Retrieval and absorption require different fixes; most pages clear retrieval but fail absorption. |
| Answer-first structure | Pages with FAQPage schema appear more frequently in top-three citation positions compared to standard articles. |
| Freshness matters | A majority of top Perplexity citations show a visible publish or update date within a recent timeframe. |
| Reddit drives citations | Reddit accounts for about 24% of all Perplexity citations, making community presence a direct citation lever. |
| Trystellor automates the system | Trystellor tracks citation rates weekly across Perplexity, ChatGPT, Claude, and Gemini, and runs the content, backlinks, and Reddit engagement that build citation share. |